
Abstract / Overview
This article explains how Large Language Model (LLM) memory works at a technical level. It breaks down internal vs. external memory, short-term vs. long-term memory, and how modern applications implement memory using embeddings, vector search, and retrieval pipelines. It includes a complete hybrid RAG + memory implementation using Python and a minimal vector database. A developer-focused architecture diagram demonstrates how memory interacts with input pipelines and LLM inference layers. A final workflow JSON snippet shows how to orchestrate this pattern in production.
Conceptual Background
What “memory” means in LLM systems
LLMs do not store memory inside model parameters the way humans do.
Memory exists in external systems, not within the model’s weights.
Three primary memory layers
LLM memory can be broken into:
1. Ephemeral memory (context window)
Lives only during the prompt.
Deleted when the conversation ends.
Limited by the model’s token window (e.g., 128k or 1M tokens).
2. Internal latent “knowledge” (model weights)
Learned during training.
Not updateable without fine-tuning or RLHF.
Not “memory” in the human sense—more like pattern storage.
3. External memory (retrieval + storage)
Vector databases (Chroma, Pinecone, Weaviate, Milvus).
Key-value stores (Redis).
JSON/DB-backed memory layers.
Long-term, persistent memory.
Most production LLM apps combine all three.
LLM Memory Architecture (Developer View)
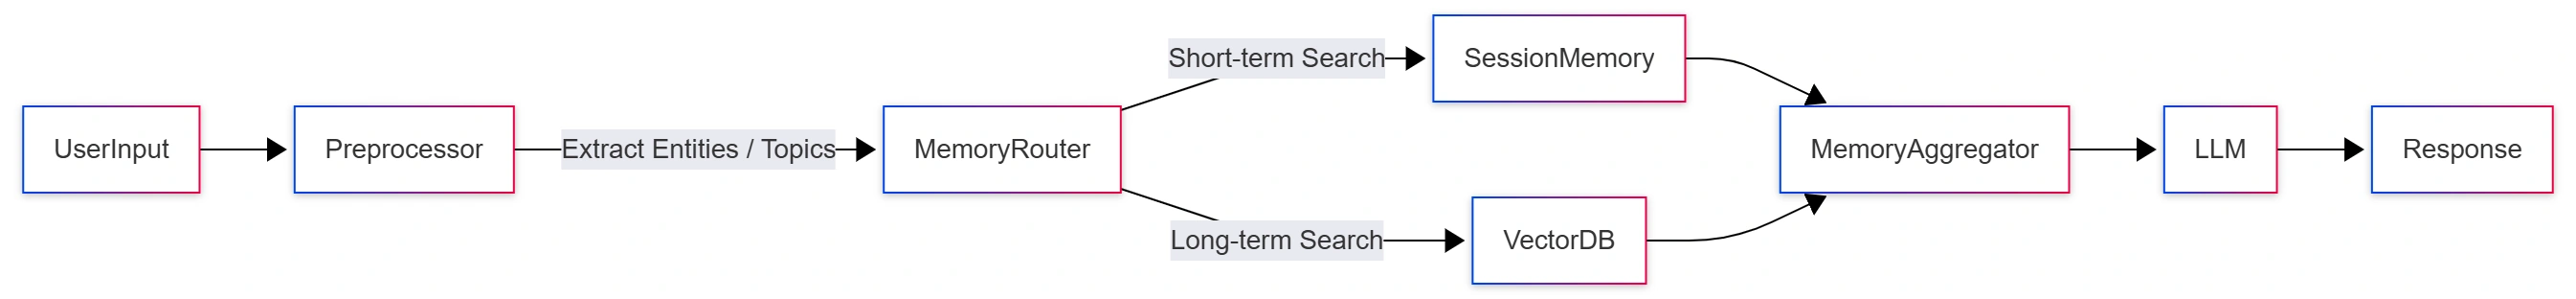
Types of LLM Memory
1. Short-Term Memory (Session Memory)
Used to maintain conversation continuity.
Typical implementation:
Sliding window of recent interactions
Token-limited memory buffer
Structured session logs
2. Long-Term Memory
Persists across sessions.
Powered by:
Embeddings → vector similarity search
Metadata tagging
Time-weighted retrieval
Recency + relevance scoring
3. Semantic Memory
Stores meaning rather than raw text.
Example:
“User likes Rust and hates Python indentation.”
Stored as:
{
  "intent": "user_preference",
  "language_like": ["Rust"],
  "language_dislike": ["Python"]
}
4. Episodic Memory (User-specific history)
Events, decisions, and actions linked to timestamps.
5. Instructional Memory
User-defined rules such as:
“Always answer concisely.”
How Memory Retrieval Works (Step-by-Step)
Step 1 — Extract entities & topics
NLP pipeline
Named Entity Recognition (NER)
Keyword extraction
Embedding generation
Step 2 — Query memory stores
Recent context → session memory
Long-term knowledge → vector DB
Domain knowledge → RAG documents
Step 3 — Merge memory chunks
Common operators:
Weighted scoring
Deduplication
Recency boosts
Relevance filters
Step 4 — Inject memory into the LLM prompt
Delivered as:
System prompt
Context blocks
Structured JSON
Step 5 — LLM generates a response using the combined memory
Full Hybrid RAG + Memory Retrieval Implementation
The following is a complete working example using:
Sentence Transformers for embeddings
FAISS as vector storage
SQLite for long-term memory key-value storage
Combined retrieval: session memory + vector memory + RAG documents
Install dependencies
pip install faiss-cpu sentence-transformers openai chromadb sqlalchemy1. Embedding model initialization
from sentence_transformers import SentenceTransformer
embedder = SentenceTransformer("all-MiniLM-L6-v2")
2. FAISS vector DB setup
import faiss
import numpy as np

dimension = 384
index = faiss.IndexFlatL2(dimension)

vector_memory = []   # store raw text
3. SQLite long-term memory table
from sqlalchemy import create_engine, Column, String, Table, MetaData

engine = create_engine("sqlite:///memory.db")
meta = MetaData()

long_term = Table(
    "long_term", meta,
    Column("key", String, primary_key=True),
    Column("value", String)
)
meta.create_all(engine)
4. Insert memory into FAISS + SQLite
def add_memory(text):
    vec = embedder.encode([text])
    index.add(np.array(vec).astype("float32"))
    vector_memory.append(text)

def add_long_term(key, value):
    with engine.connect() as conn:
        conn.execute(long_term.insert().values(key=key, value=value))
5. Retrieve top-k from FAISS memory
def search_memory(query, k=3):
    vec = embedder.encode([query]).astype("float32")
    scores, ids = index.search(vec, k)
    results = [vector_memory[i] for i in ids[0] if i < len(vector_memory)]
    return results
6. Retrieve long-term memory from SQLite
def load_long_term(key):
    with engine.connect() as conn:
        result = conn.execute(long_term.select().where(long_term.c.key == key))
        row = result.fetchone()
        return row.value if row else None
7. RAG document retrieval (Chroma example)
import chromadb
chroma = chromadb.Client()

rag_collection = chroma.create_collection("docs")

def rag_search(query):
    return rag_collection.query(query_texts=[query], n_results=3)["documents"]
8. Hybrid retrieval pipeline
def retrieve_hybrid(query, session_history):
    session_context = session_history[-3:] if session_history else []

    vector_results = search_memory(query)
    rag_results = rag_search(query)

    merged = {
        "session": session_context,
        "vector_memory": vector_results,
        "rag_docs": rag_results,
        "long_term": load_long_term("user_profile")
    }

    return merged
9. Build final LLM prompt
def build_prompt(query, memory):
    return f"""
SYSTEM:
You have access to session, long-term memory, vector memory, and RAG documents.
Use them to provide accurate answers.

MEMORY:
Session: {memory['session']}
Long-term: {memory['long_term']}
Vector Memory: {memory['vector_memory']}
RAG Docs: {memory['rag_docs']}

USER QUERY:
{query}
"""
10. Execute LLM request
from openai import OpenAI
client = OpenAI(api_key="YOUR_API_KEY")

def ask_llm(prompt):
    completion = client.chat.completions.create(
        model="gpt-4.1",
        messages=[{"role": "user", "content": prompt}]
    )
    return completion.choices[0].message["content"]
Usage
session_history = []
query = "What did I say about my preferred programming language?"

memory = retrieve_hybrid(query, session_history)
prompt = build_prompt(query, memory)

response = ask_llm(prompt)
print(response)
Use Cases / Scenarios
Personal AI assistant with evolving user profile
Customer-service chatbots with persistent conversation logs
Corporate knowledge management systems
Autonomous agents requiring episodic memory
AI copilots that remember project-specific decisions
Limitations / Considerations
Memory must be curated, or it becomes noisy.
Vector DBs require embedding consistency across updates.
Long-term memory risks hallucinations if not validated.
Memory overflow requires pruning strategies.
Fixes (Common Pitfalls)
Problem: Memory grows indefinitely
Fix: Size-based pruning, time-weighting, importance scoring
Problem: Irrelevant retrieval
Fix: Relevance threshold + hybrid scoring (recency × similarity)
Problem: LLM overfits to user memory
Fix: Memory gating:
{ "memory_allowed": true, "memory_reasoning_required": false }FAQs
How is memory different from context?
Context = temporary.
Memory = external & persistent.
Do LLMs “remember” by themselves?
No. Apps must add memory infrastructure.
Is memory stored inside the model weights?
No. Only training knowledge lives in weights.
Can LLM memory be updated in real time?
Yes—via vector DBs and metadata stores.
References
FAISS documentation
SentenceTransformers framework
OpenAI Retrieval APIs
ChromaDB docs
Research papers on memory-augmented LLMs
Conclusion
LLM memory is not an internal mechanism—it’s an engineered system. Developers build memory layers using vector search, structured storage, and retrieval pipelines that merge short-term and long-term data. Hybrid RAG + memory systems are now the standard pattern for AI copilots, agents, and assistants. This article provided a production-grade architecture, code implementation, and memory workflow for real applications.
Join the conversation! Your thoughts help the community grow.