
In this article I am trying to share a piece of code that might be useful to
some of the developers.
We can find a lot of code in C# that will parse the http urls in given string.
But it is difficult to find a code that will:
- Accept a url as argument, parse the site content
- Fetch all urls in the site content, parse the site content of each urls
- Repeat the above process until all urls are fetched.
Scenario
Taking the website http://valuestocks.in
(A Stock Market Site) as example I would like to get all the urls inside the
website recursively.
Design
The main class is SpiderLogic which contains all necessary methods and
properties.
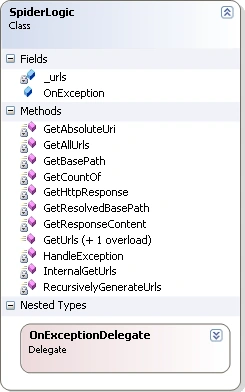
The GetUrls() method is used to parse the website and return the urls. There are
two overloads for this method.
The first one takes 2 arguments. The url and and a Boolean indicating if
recursive parsing is needed or not.
E.g.: GetUrls(http://www.google.com", true);
The second one is 3 arguments, url, base url and recursive Boolean.
This method is intended for usage like the url is a sub level of the base url.
And the web page contains relative paths. So in order to construct the valid
absolute urls, the second argument is necessary.
E.g.: GetUrls("http://www.whereincity.com/india-kids/baby-names/
", http://www.whereincity.com/ ,
true);
Method Body of GetUrls()
public
IList<string>
GetUrls(string url,
string baseUrl,
bool
recursive)
{
if (recursive)
{
_urls.Clear();
RecursivelyGenerateUrls(url, baseUrl);
return _urls;
}
else
return InternalGetUrls(url,
baseUrl);
}
InternalGetUrls()
Another method of interest would be InternalGetUrls() which fetches the content
of url, parses the urls inside it and constructs the absolute urls.
private
IList<string>
InternalGetUrls(string baseUrl,
string absoluteBaseUrl)
{
IList<string>
list = new List<string>();
Uri uri = null;
if (!Uri.TryCreate(baseUrl,
UriKind.RelativeOrAbsolute,
out uri))
return list;
// Get the http content
string siteContent =
GetHttpResponse(baseUrl);
var allUrls = GetAllUrls(siteContent);
foreach (string uriString
in allUrls)
{
uri = null;
if (Uri.TryCreate(uriString,
UriKind.RelativeOrAbsolute,
out uri))
{
if (uri.IsAbsoluteUri)
{
if (uri.OriginalString.StartsWith(absoluteBaseUrl))
// If different domain / javascript: urls needed
exclude this check
{
list.Add(uriString);
}
}
else
{
string newUri =
GetAbsoluteUri(uri, absoluteBaseUrl, uriString);
if (!string.IsNullOrEmpty(newUri))
list.Add(newUri);
}
}
else
{
if (!uriString.StartsWith(absoluteBaseUrl))
{
string newUri =
GetAbsoluteUri(uri, absoluteBaseUrl, uriString);
if (!string.IsNullOrEmpty(newUri))
list.Add(newUri);
}
}
}
return list;
}
Handling Exceptions
There is an OnException delegate that can be used to get the exceptions
occurring while parsing.
Tester Application
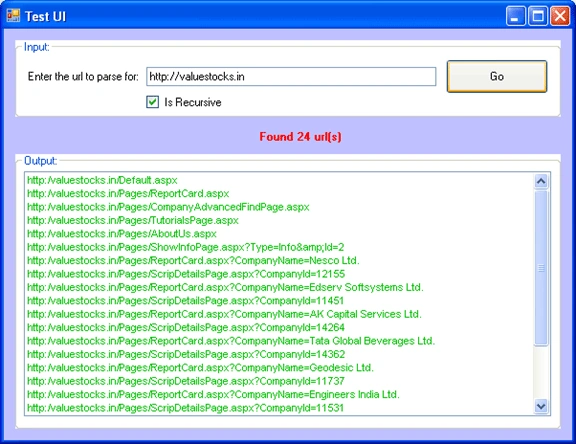
A tester windows application is included with the source code of the article.
You can try executing it.
The form accepts a base url as the input and clicking the Go button it parses
the content of url and extracts all urls in it. If you need a recursive parsing
please check the Is Recursive check box.
Next Part
In the next part of the article, I would like to create a url verifier website
that verifies all the urls in a website. I agree after doing a search we can
find free providers like that. My aim is to learn & develop a custom code that
could be extensible and reusable across multiple projects by community.
Haswell VAPosted Feb 15, 2017, 4:56 AM
I have a mather... The Url start by http:/ and for use the url with the method URI it need to be http://. How can I correct it ?
rosepriya johnPosted Sep 9, 2015, 5:25 AM
Good work. Nice coding and helpful also...
Mitul AhirPosted Aug 14, 2014, 3:35 PM
Can you please advise me how I can do similar things with HTML file? I have an HTML that has a hyperlink which points to another hyperlink, and that hyperlink points to some other. So I have so many levels but in folder, not on website. So there is no http:'// in hyperlink part. For example: href=123.html
S ParuiPosted Nov 18, 2012, 8:57 AM
http://www.planetexim.net..this is my website
Jean PaulPosted Nov 16, 2012, 12:23 PM
Which is your web site url? Send me the details to jeanpaulvaATgmailDOTTTTTcom Please send me the non-included url too. Thanks Jean Paul
S ParuiPosted Nov 16, 2012, 2:04 AM
I am not able to get all url list of my site.Its returning only 40 urls of my site. But there are more than 2000 pages in my site. So please tell me how to get all the url list. Thanks in advance.
sachinPosted Oct 7, 2012, 8:37 AM
let me try working with your application. Dude I need your expertise. Can you email me to [email protected]. I am waiting for your reply.
Jean PaulPosted Aug 3, 2012, 9:26 AM
Yeah! good idea.. you can add new Thread(new ThreadStart()) for this or BackgroundWorker
yunus farooquiPosted Aug 3, 2012, 7:22 AM
Thanks for sharing . It would be helpful if you give idea to implement the logic with multithreading so tht execution would be faster thanks.
yunus farooquiPosted Aug 3, 2012, 7:20 AM
It is really nice program . It would be very helpful if you give idea to write this programe using multithreading so that execution would be much faster Thanks
Jean PaulPosted Jul 24, 2012, 9:16 AM
You're Welcome Veeekay
Veekay PandeyPosted Jul 24, 2012, 2:58 AM
It is really nice program. But I am actually searching for the contact information extraction from different web sites. It will be really nice if you provide some information about that. Thank you in advance..
Sam HobbseditedPosted Mar 28, 2011, 4:23 PMEdited Mar 28, 2011, 4:26 PM
I know that many people use RegularExpressions to parse HTML. Thank you for showing how to get all the urls in a website using RegularExpressions. I prefer to use the DOM though. The HTML can be put in a HtmlDocument and the Links Property can be used to get all the links in a web page. A lot of your code, such as recursion, is still useful even if the HtmlDocument class was used instead of RegularExpressions.